What counts as duplicate content?
Duplicate content is any block of main content that search engines can reach under two or more URLs. Google groups such pages into a cluster and shows only one of them, a process often called deduplication. The duplicate can be exact (the same page with ?utm_source=newsletter) or near-duplicate (two category pages that differ only in sort order). Translations are not duplicates, provided the main content is actually translated; a page with only the header and footer translated still counts as a duplicate.
5 common causes of duplicate content
Google Search Central names 5 typical sources of duplicate URLs, and most of them are technical, not editorial:
- Region variants: the same English text for the US, UK and Australia on separate URLs.
- Device variants: separate mobile (m.) and desktop pages.
- Protocol variants: HTTP and HTTPS, or www and non-www versions.
- Site functions: sorting, filtering and pagination in shop categories.
- Accidental variants: staging or demo sites left open to crawlers.
Bing adds URL parameters, trailing slashes, capitalisation, print versions and large-scale syndication to the list.
Is there a duplicate content penalty?
There is no automatic penalty for duplicate content, but there is a loss of visibility. Google says some duplication is normal and not a violation of its spam policies; Bing wrote in December 2025 that duplicates do not trigger penalties on their own. The cost is indirect: links and engagement split across URLs, Google may show a URL you did not choose, and crawlers waste crawl budget on copies. The exception is deliberate copying. Google’s spam policies treat scraped content, meaning republished text from other sites with no added value, as spam.
Duplicate content on international sites
International sites create duplicates whenever two markets share one language: de-DE, de-AT and de-CH, or en-GB and en-US. Google’s multi-regional guide recommends picking a preferred version and combining a canonical tag with hreflang. Each version keeps a self-referencing canonical, and hreflang tells Google which one to show in which country. Bing goes further and advises making regional pages really different, with local terminology, regulations, examples and product details.
In my German and Austrian projects, the Austrian pages that only swap “Euro inkl. MwSt.” for the same text usually get clustered with the German ones. Pages with local shipping, prices and legal notes stay separate. The same happens with Czech and Slovak shops built from one template, so localisation is the real fix, not just tags.
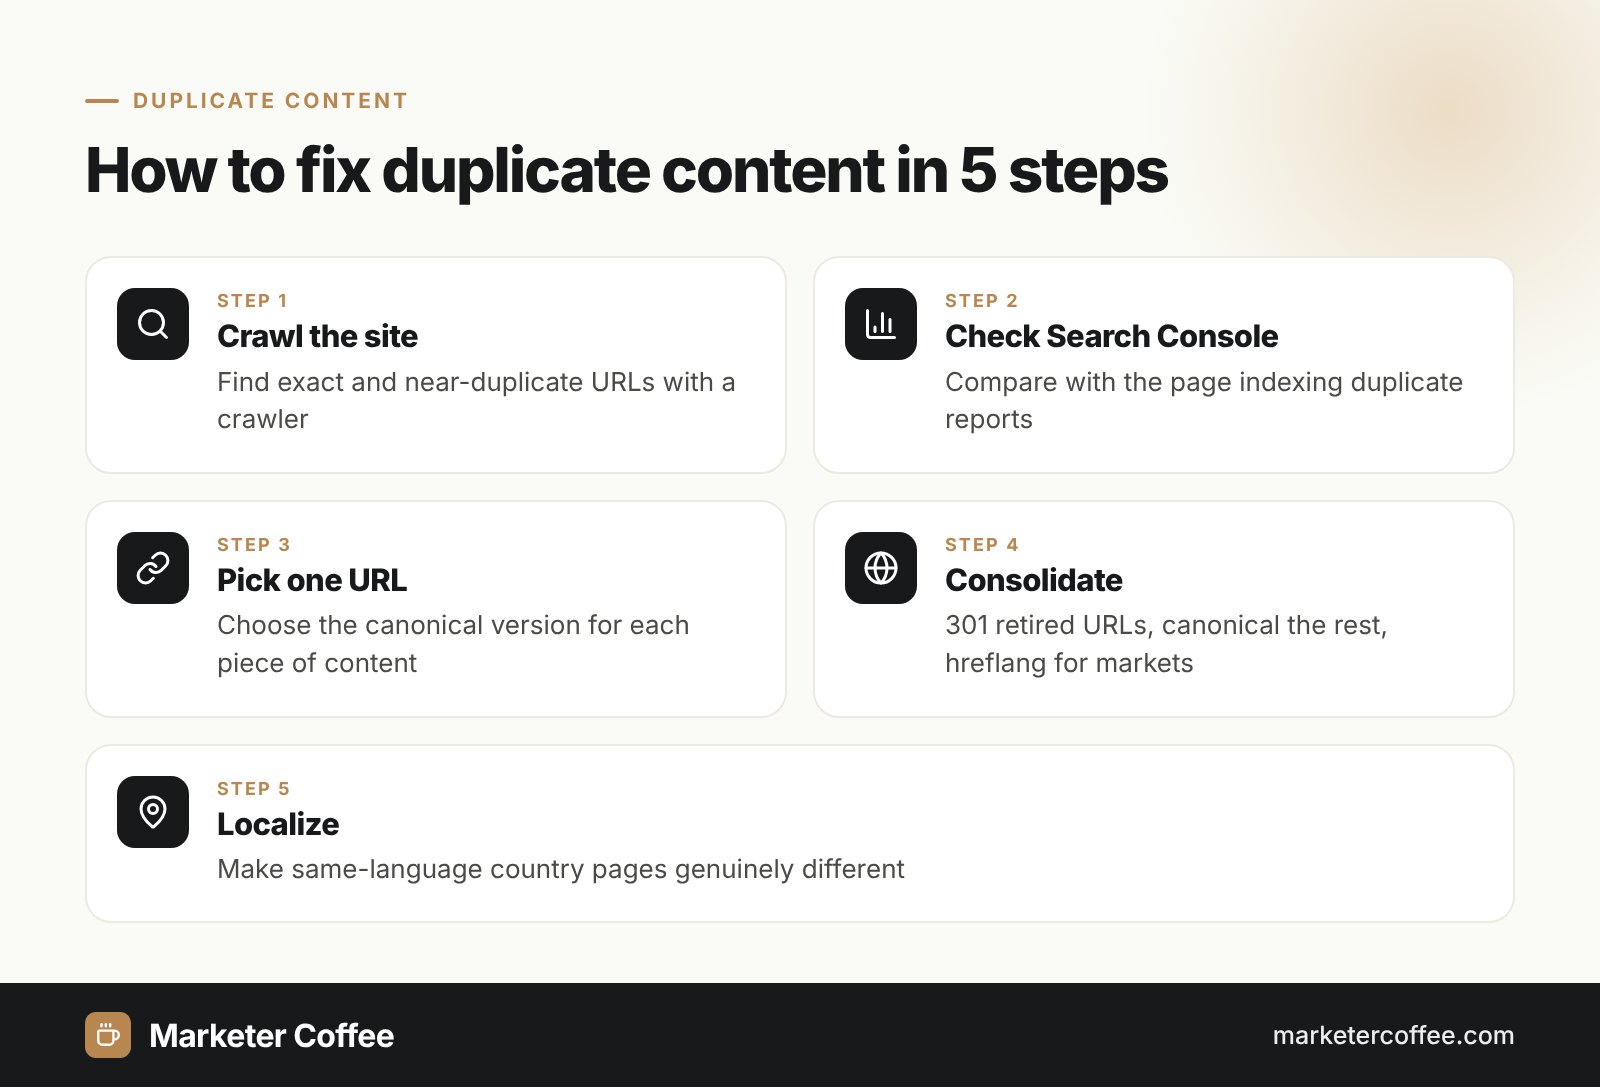
How to fix duplicate content
You fix duplicate content by choosing one URL per piece of content and pointing every other signal at it. The table matches each situation with the right tool:
| Situation | Fix |
|---|---|
| Old or merged page | 301 redirect to the main URL |
| Filters, UTM, print versions | rel=”canonical” to the clean URL |
| Same-language country versions | Self-canonical plus hreflang, localized content |
| Staging or internal search pages | noindex or password protection |
| Syndicated articles | Cross-domain canonical or excerpt with link back |
Google also warns against 2 popular shortcuts: blocking duplicates in robots.txt (Googlebot then cannot see the canonical) and using noindex to choose a canonical within one site. Duplicate pages that target the same query create a related problem, keyword cannibalization.
Duplicate content and AI search
Duplicate content hurts AI visibility because AI answers are built on the same index and the same canonical choice. Bing explains that large language models group near-duplicate URLs into one cluster and may pick an outdated page as its representative. A page that is not the chosen canonical has little chance of being cited in Copilot, AI Overviews or ChatGPT search results.
Duplicate content is a standard part of every SEO audit I run and a recurring issue in international SEO projects.
Frequently asked questions about Duplicate content
Does Google penalize duplicate content?
Google does not penalize ordinary duplicate content. It filters duplicates and shows one version, but scraped content copied from other sites without added value can violate its spam policies.
Are translated pages duplicate content?
Fully translated pages are not duplicate content. Google treats pages as duplicates only when the main content is in the same language, for example when only the menu is translated.
How much duplicate content is acceptable?
Google gives no percentage threshold. Some duplication, such as legal notices or product specs, is normal; what matters is that each page has one clear canonical URL.
How do I find duplicate content on my site?
Check the page indexing report in Google Search Console and run a site crawler with near-duplicate detection. Both show which URLs Google or the crawler groups together.
Related terms
- What is URL canonicalization · Google Search Central
- How to specify a canonical URL with rel="canonical" and other methods · Google Search Central
- Managing multi-regional and multilingual sites · Google Search Central
- Spam policies for Google web search · Google Search Central
- Does Duplicate Content Hurt SEO and AI Search Visibility? · Bing Webmaster Blog